Production numbers below come from DeepSeek’s published inference Q&A / public explainers. They describe the production inference system , not the outcome of installing OSS DeepInfer alone.
Architecture overview
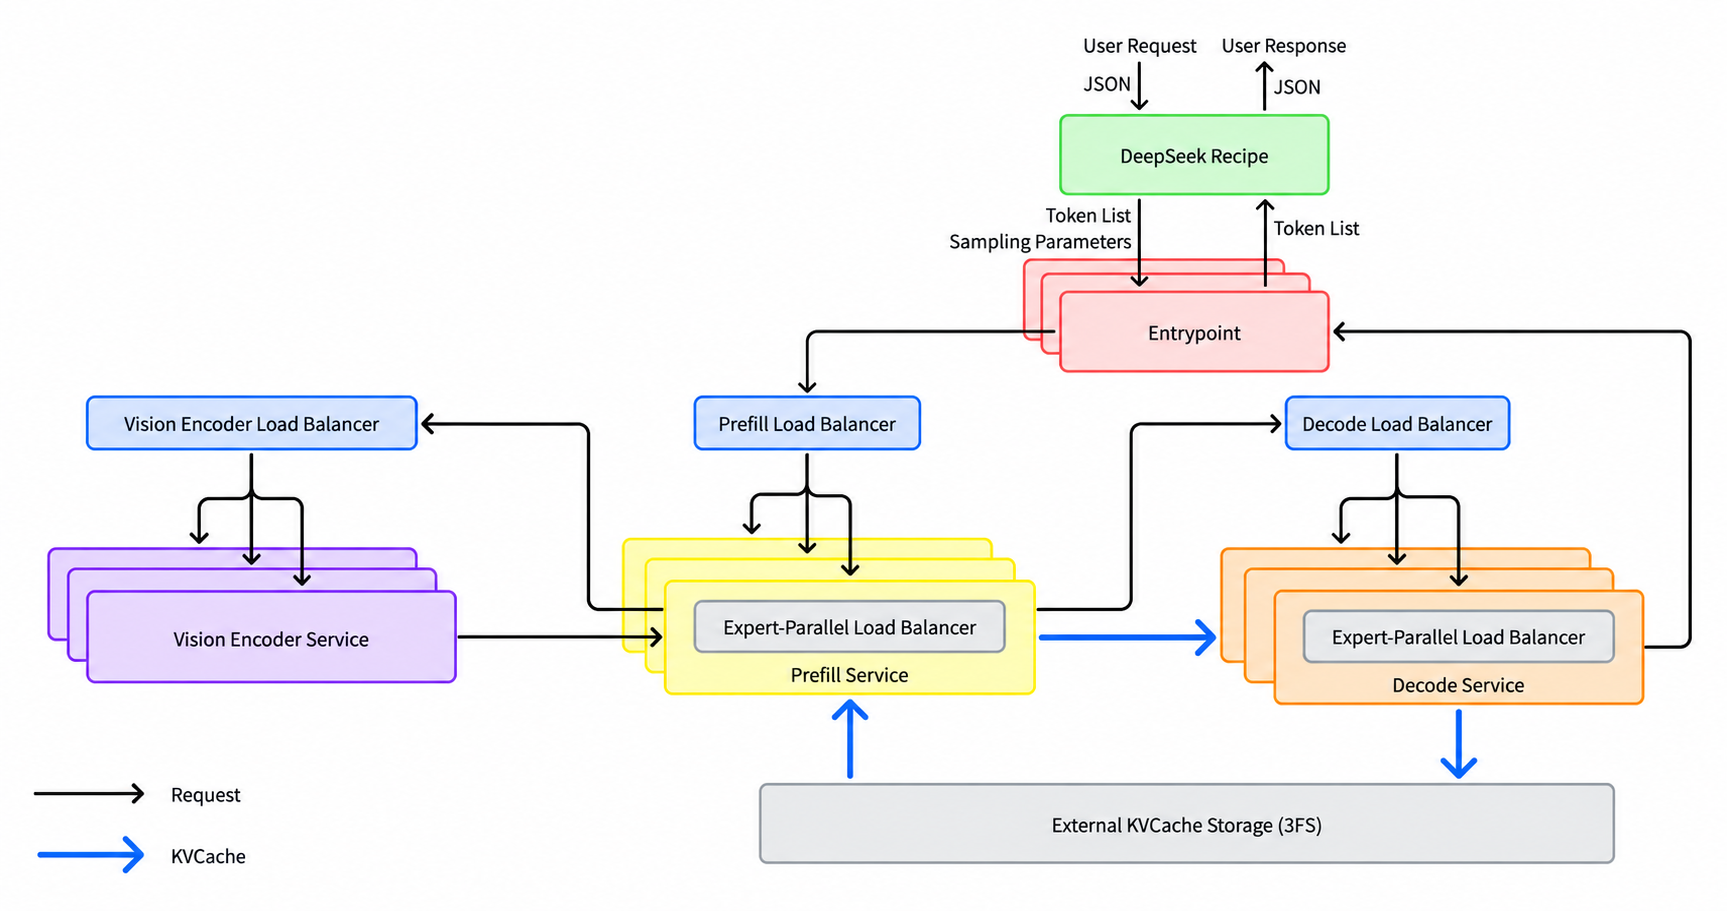
Official architecture overview — DeepInfer doc/images/architecture_overview.png (Apache-2.0)
Request path (conceptual)
Step Component What happens In OSS?
1 API / recipe Messages · Chat Completions · Responses → Conversation → tokens recipe is separate MIT repo 2 Entrypoint / cache match Prefix / KV hit length before routing KV store not OSS 3 Prefill engine Compute non-cached suffix; write KV engine yes; service glue no 4 Decode engine Autoregressive tokens; Wide-EP MoE engine yes; LB/disagg no 5 Sampler / DSpark Draft + confidence-scheduled verify flags in README 6 recipe parse Token stream → protocol events (reasoning / tools / text) recipe yes
Production snapshot (attribution required)
Metric Reported value Label
Cluster tokens/day ~155 trillion Production system Valley revenue ~US$38 / GPU-hour Production system Avg input · cache hit ~77K · ~96% Production system TTFT ~400 ms avg Production system Prefill no-cache → cache ~60k → ~1.5M tok/s/GPU (~25×) Production system Decode · user speed ~14k tok/s/GPU · ~230 tok/s (~300 code) Production system Efficient unit ~64P + 64D · P:D ≈ 1:1 Production / Q&A
OSS gap callout
Open-source DeepInfer: offline engine + kernels + EP/DP/CP examples
Not included: KV cache system, full PD-disagg serving, DP load balancers
No official Docker image — community Dockerfiles are examples only
Hardware today: SM100 (CUDA 13) · Ascend 950 (CANN 9.2)
Continue: install · hardware · vs vLLM · recipe · FAQ .
Sources: inference_deployment_qa.md · README · public WeChat explainers (rewritten)