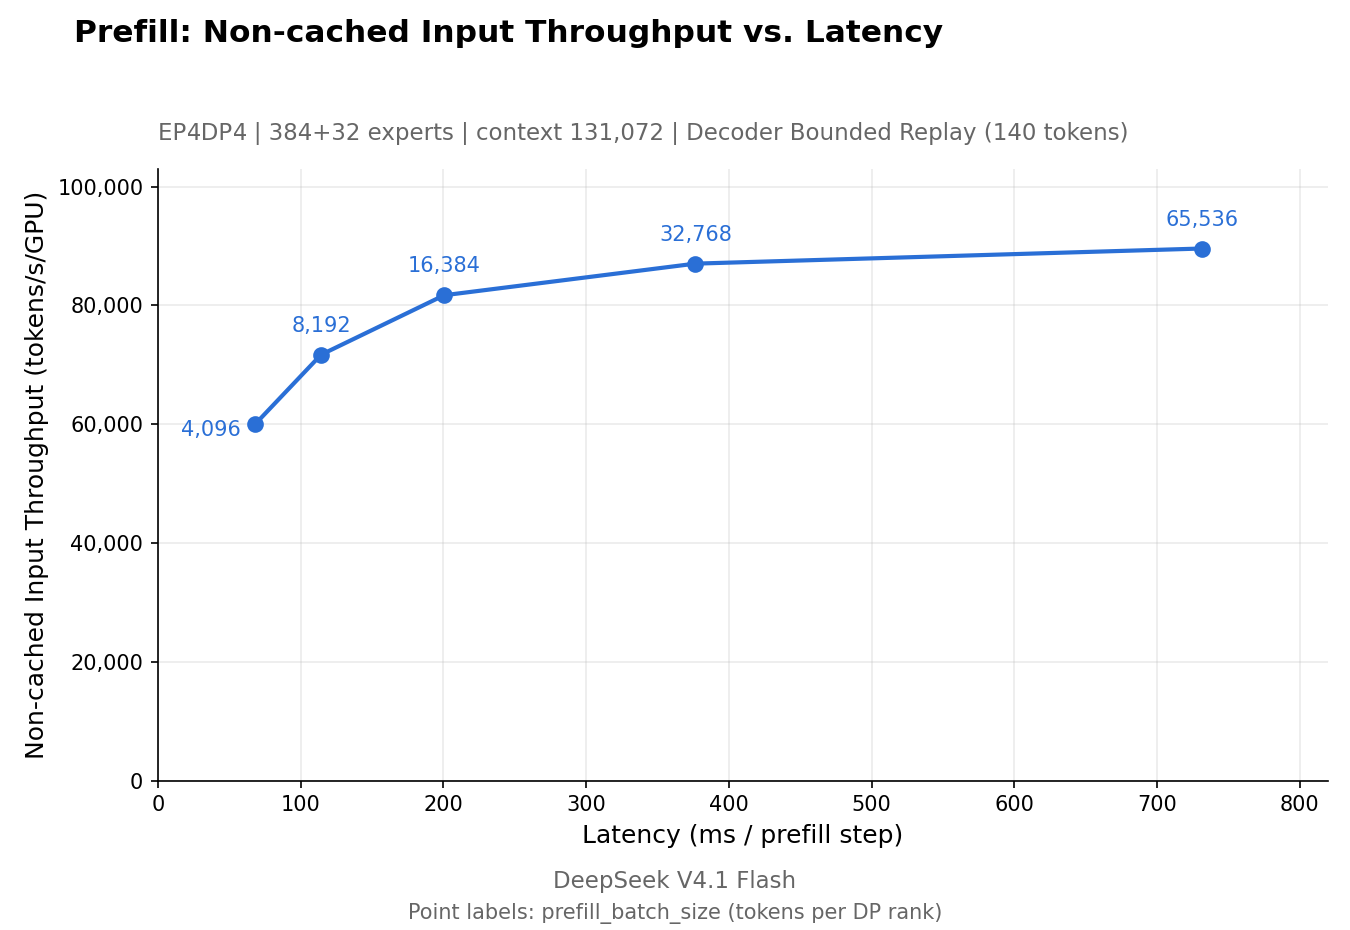
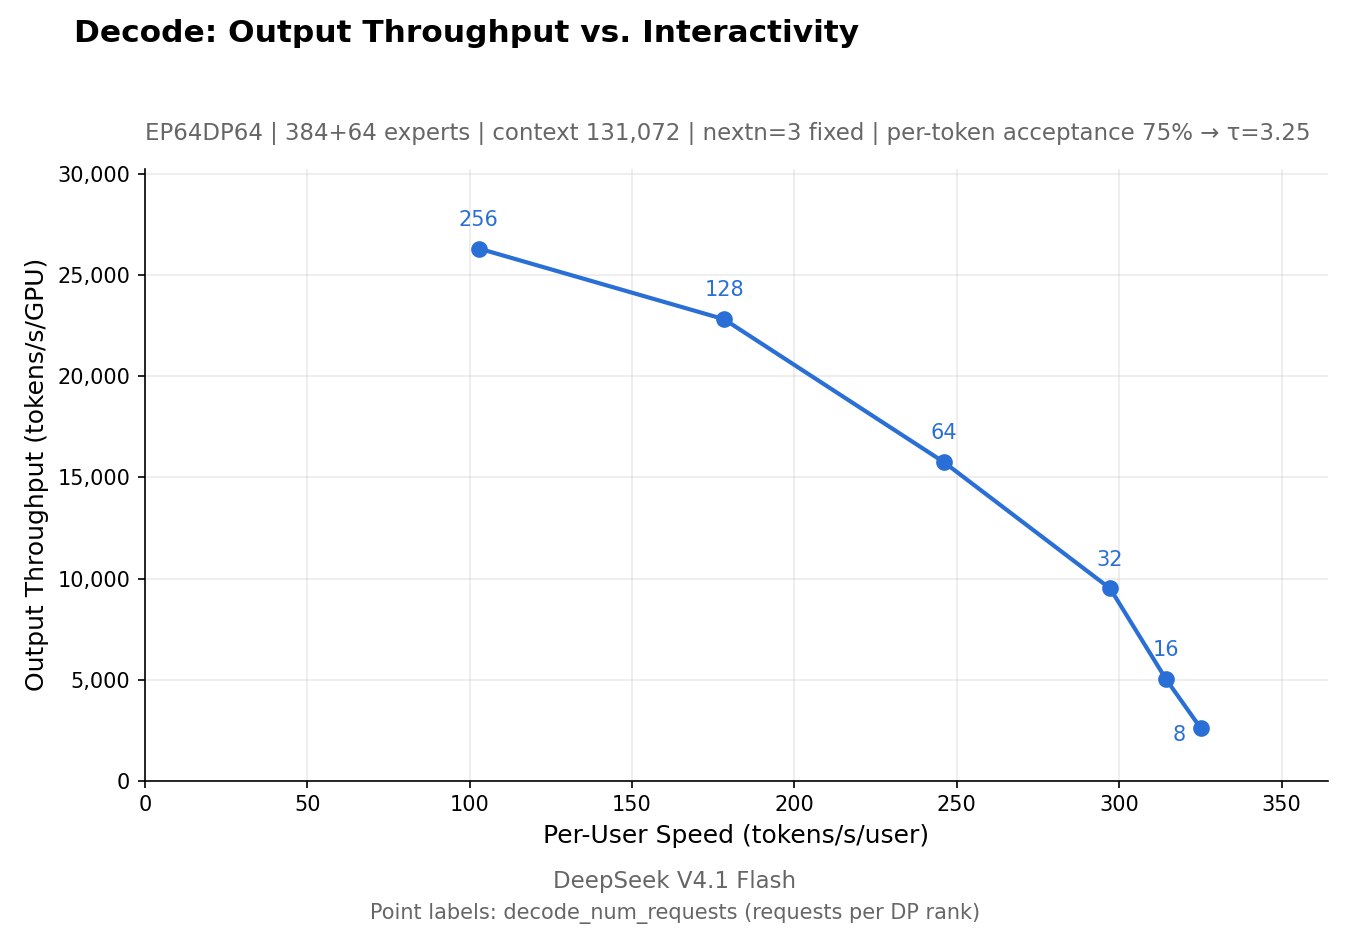
Prefill and Decode charts are two phases of one DeepInfer engine — not two products. Machine-level PD disaggregation is production serving glue and is not fully open-sourced.
Same engine, two phases
Phase
Focus
README sweep topology
Prefill
Input throughput vs latency
4× SM100 · one scale-up domain
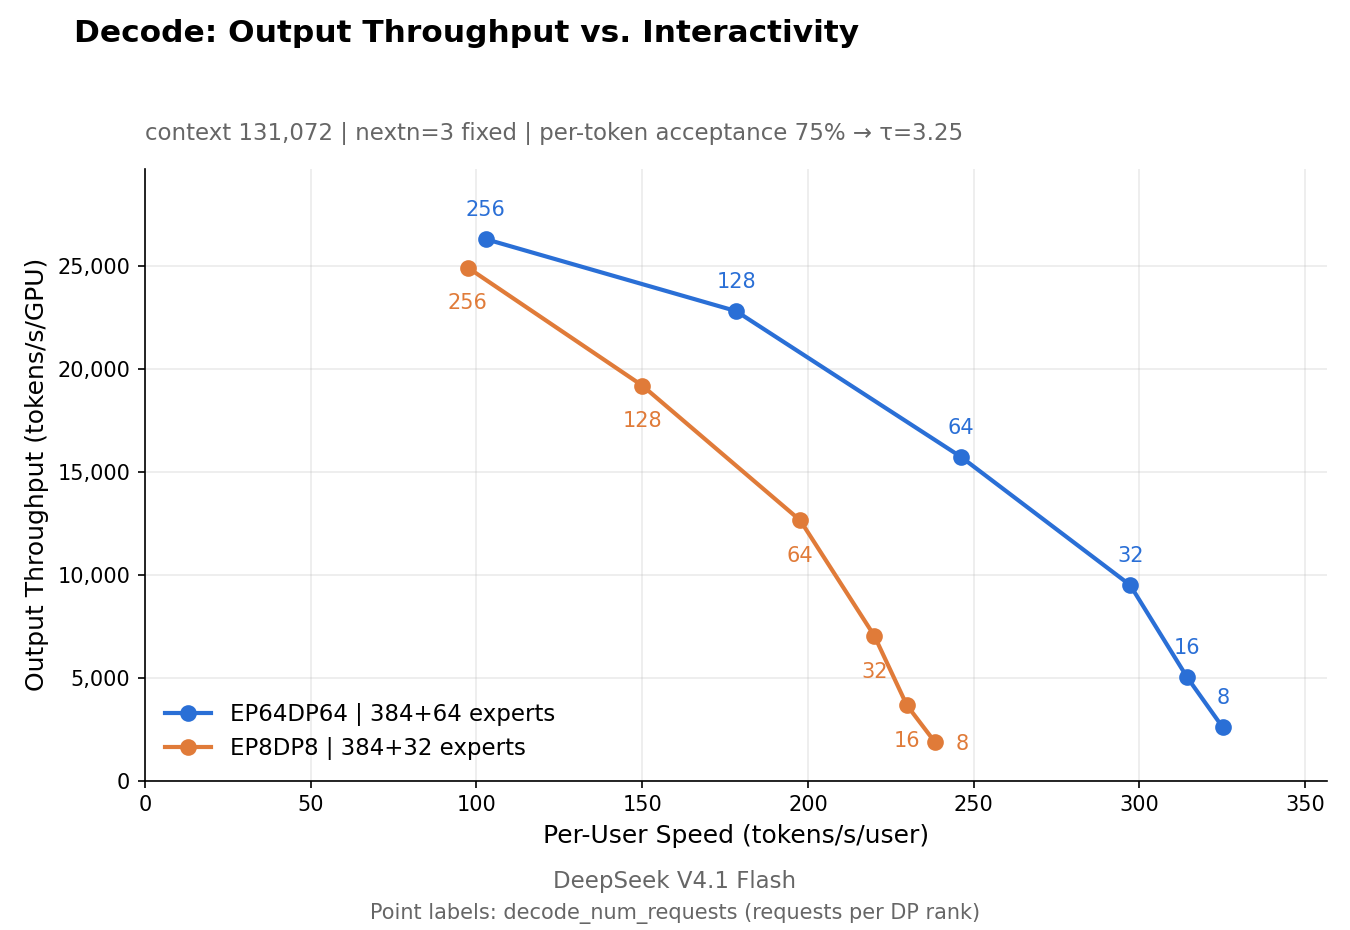
Decode
Output throughput vs per-user speed
64× SM100 · one scale-up domain
Official prefill Pareto (DeepInfer doc/images)Official decode Pareto (DeepInfer doc/images)
OSS vs production gaps
Layer
OSS DeepInfer
Production system (Q&A)
Engine phases P/D
Same binary / offline path
Same conceptual stages
PD across machines + LB
Not included
Disaggregated E/P/D + balancers
Long-retention KV (3FS)
Not included
Dedicated storage cluster
Wide-EP decode
EP/DP APIs in offline examples
EP64–128 typical
Parallelism ranges (Q&A — with caveats)
Caveat. Ranges below describe the production deployment discussed in inference_deployment_qa.md. They are planning context, not “defaults after ./build.sh”.
Stage
Parallelism (production Q&A)
Guidance
Prefill
EP2–8 / DP2–8
Smallest EP/DP HBM allows
Decode
EP64–128 / DP64–128 (Wide-EP)
Largest EP/DP available GPUs allow
VE
Often 1 GPU / instance
Cheaper GPUs recommended
TP / CP
Not used for now (Q&A)
OSS examples still expose --cp for offline
Wide-EP decode chart from official doc/images — production/benchmark context